African AI Model Highlights Data Gap Despite Access to Supercomputing
Vambo AI developed MORENA, a 1.5-billion-parameter model covering 12 African languages, but says the shortage of high-quality real-language text made synthetic data necessary for much of its training.
Johannesburg-based Vambo AI has developed MORENA, a 1.5-billion-parameter model covering 12 African languages alongside English, French and code. The project demonstrates both the potential of African-language artificial intelligence and the data constraints facing developers on the continent.
Table Of Content
Vambo trained MORENA from scratch rather than adapting an existing foundation model. The company said this approach was chosen because general-purpose models can carry weaknesses in their handling of African languages.
Scarcity of language data
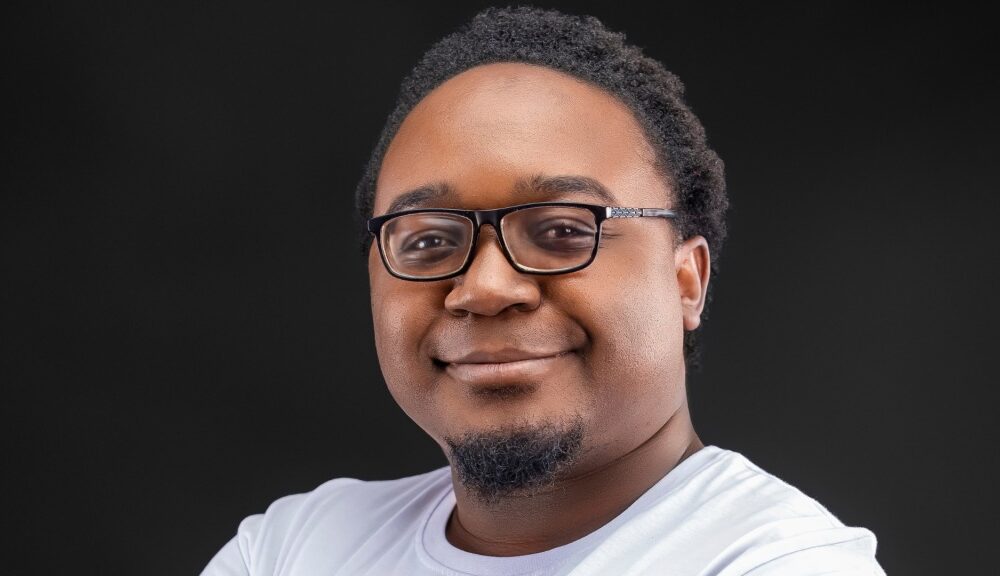
Isheanesu Misi, Vambo AI’s co-founder and chief technology officer, said the team struggled to find enough real African-language text for the project.
“Finding that much real data was close to impossible, so a lot of it was synthetic,” Misi said.
The synthetic material was also used to guide the model towards capabilities including tool calling. However, Misi said the approach introduced limitations, including language outputs whose grammar was close to correct but not fully accurate.
“You would find that some of the grammar of the outputs is close but imperfect,” he said.
MORENA covers ChiShona, Kiswahili, Hausa, Yorùbá, Igbo, isiZulu, isiXhosa, Kinyarwanda, Setswana, Afrikaans, isiNdebele and Nigerian Pidgin. Vambo’s model documentation says the system was trained on 251.7 billion tokens, including 65.6 billion tokens in African languages.
The shortage of digitised text and speech data remains a wider obstacle for African-language AI. The gap raises concerns about whether future systems will adequately reflect the continent’s linguistic diversity or perform reliably in local languages.
Supercomputing access
Vambo used CINECA’s Leonardo supercomputer through the United Nations Development Programme’s AI Hub for Sustainable Development. Some training runs used 512 GPUs simultaneously.
TechCabal reported that the project consumed 22,000 A100 GPU-hours, estimated to be worth between $25,000 and $40,000. Vambo’s cash cost for that computing was zero because the access was provided through CINECA and the UNDP AI Hub.
Misi said access to high-performance computing was essential to the project. “Without access to that kind of compute power, this project would have been dead on arrival,” he said.
The availability of computing does not, however, resolve the shortage of relevant training material. Misi described some African languages, including isiNdebele and Nigerian Pidgin, as having “next to no resources available”.
“That means that the AI applications are extremely important and necessary, but they can’t be fully built by local innovators because they don’t have everything they need,” he said.
Open model, unreleased corpus
MORENA’s model weights are available under an Apache 2.0 licence, allowing developers to work with the released model. Its training corpus has not been released, and the identities and licensing details of the real and synthetic datasets have not been provided.
Vambo has also produced smaller versions with 0.5 billion and 0.2 billion parameters for lower-resource environments. The company has positioned MORENA as a foundation that developers can fine-tune for uses such as fintech and education rather than building a new model from the beginning.
“If everyone is to try and build a model from scratch, it’s prohibitively expensive, complicated, time-consuming,” Misi said. “But fine-tuning could cost a hundred dollars or even less at times.”
According to Vambo, MORENA recorded 1.408 bits per byte across the 12 African languages, the lowest score among 26 tested models. Its model card also says its tokeniser uses 1.39 times fewer tokens than Gemma 3 and 1.53 times fewer than Llama 3.2 when representing African-language text. The extent to which these results have been independently verified was not stated.
Other efforts are also targeting the continent’s language-data and infrastructure gaps. These include Nigeria’s N-ATLAS multilingual model, Google’s WAXAL speech dataset covering 21 sub-Saharan African languages, and initiatives involving UduTech, Chipmango and South Korean AI infrastructure company BARO AI to expand access to computing resources.
No Comment! Be the first one.